
100 of the 100 papers that shaped modern AI, from Dropout (2012) to Mamba (2023), each turned into a small, runnable, from-scratch PyTorch reimplementation with a plain-English explainer. Every notebook in this repo was executed top to bottom on Kaggle and is published with its real outputs, so you can open it, see it work, and fork it on a free GPU.
How it’s made: agent-generated, GPU-validated, human-reviewed
This repo is also an experiment in what AI agents can build when the bar is “it actually runs.”
- Curated list: I picked 100 landmark papers and wrote, for each one, a spec of what its notebook should demonstrate.
- Agent-generated: an AI agent reads the paper, writes the from-scratch implementation, and drafts the explainer docs.
- GPU-validated: every notebook is pushed to Kaggle and run end-to-end, on a T4 GPU or on CPU for the small ones. A notebook ships only if every cell runs with zero errors, and the executed version, with its outputs, is what gets committed.
- Human-reviewed: I review the code, results and claims before publishing, and re-run or rewrite the notebooks whose results don’t hold up.
Scaled down on purpose. These are teaching-sized reproductions: small models, synthetic or small datasets, minutes of training instead of days. They show how each idea works and reproduce the qualitative effect, not the paper’s headline numbers. Each
CODE_ARCHITECTURE.mdlists the simplifications made.
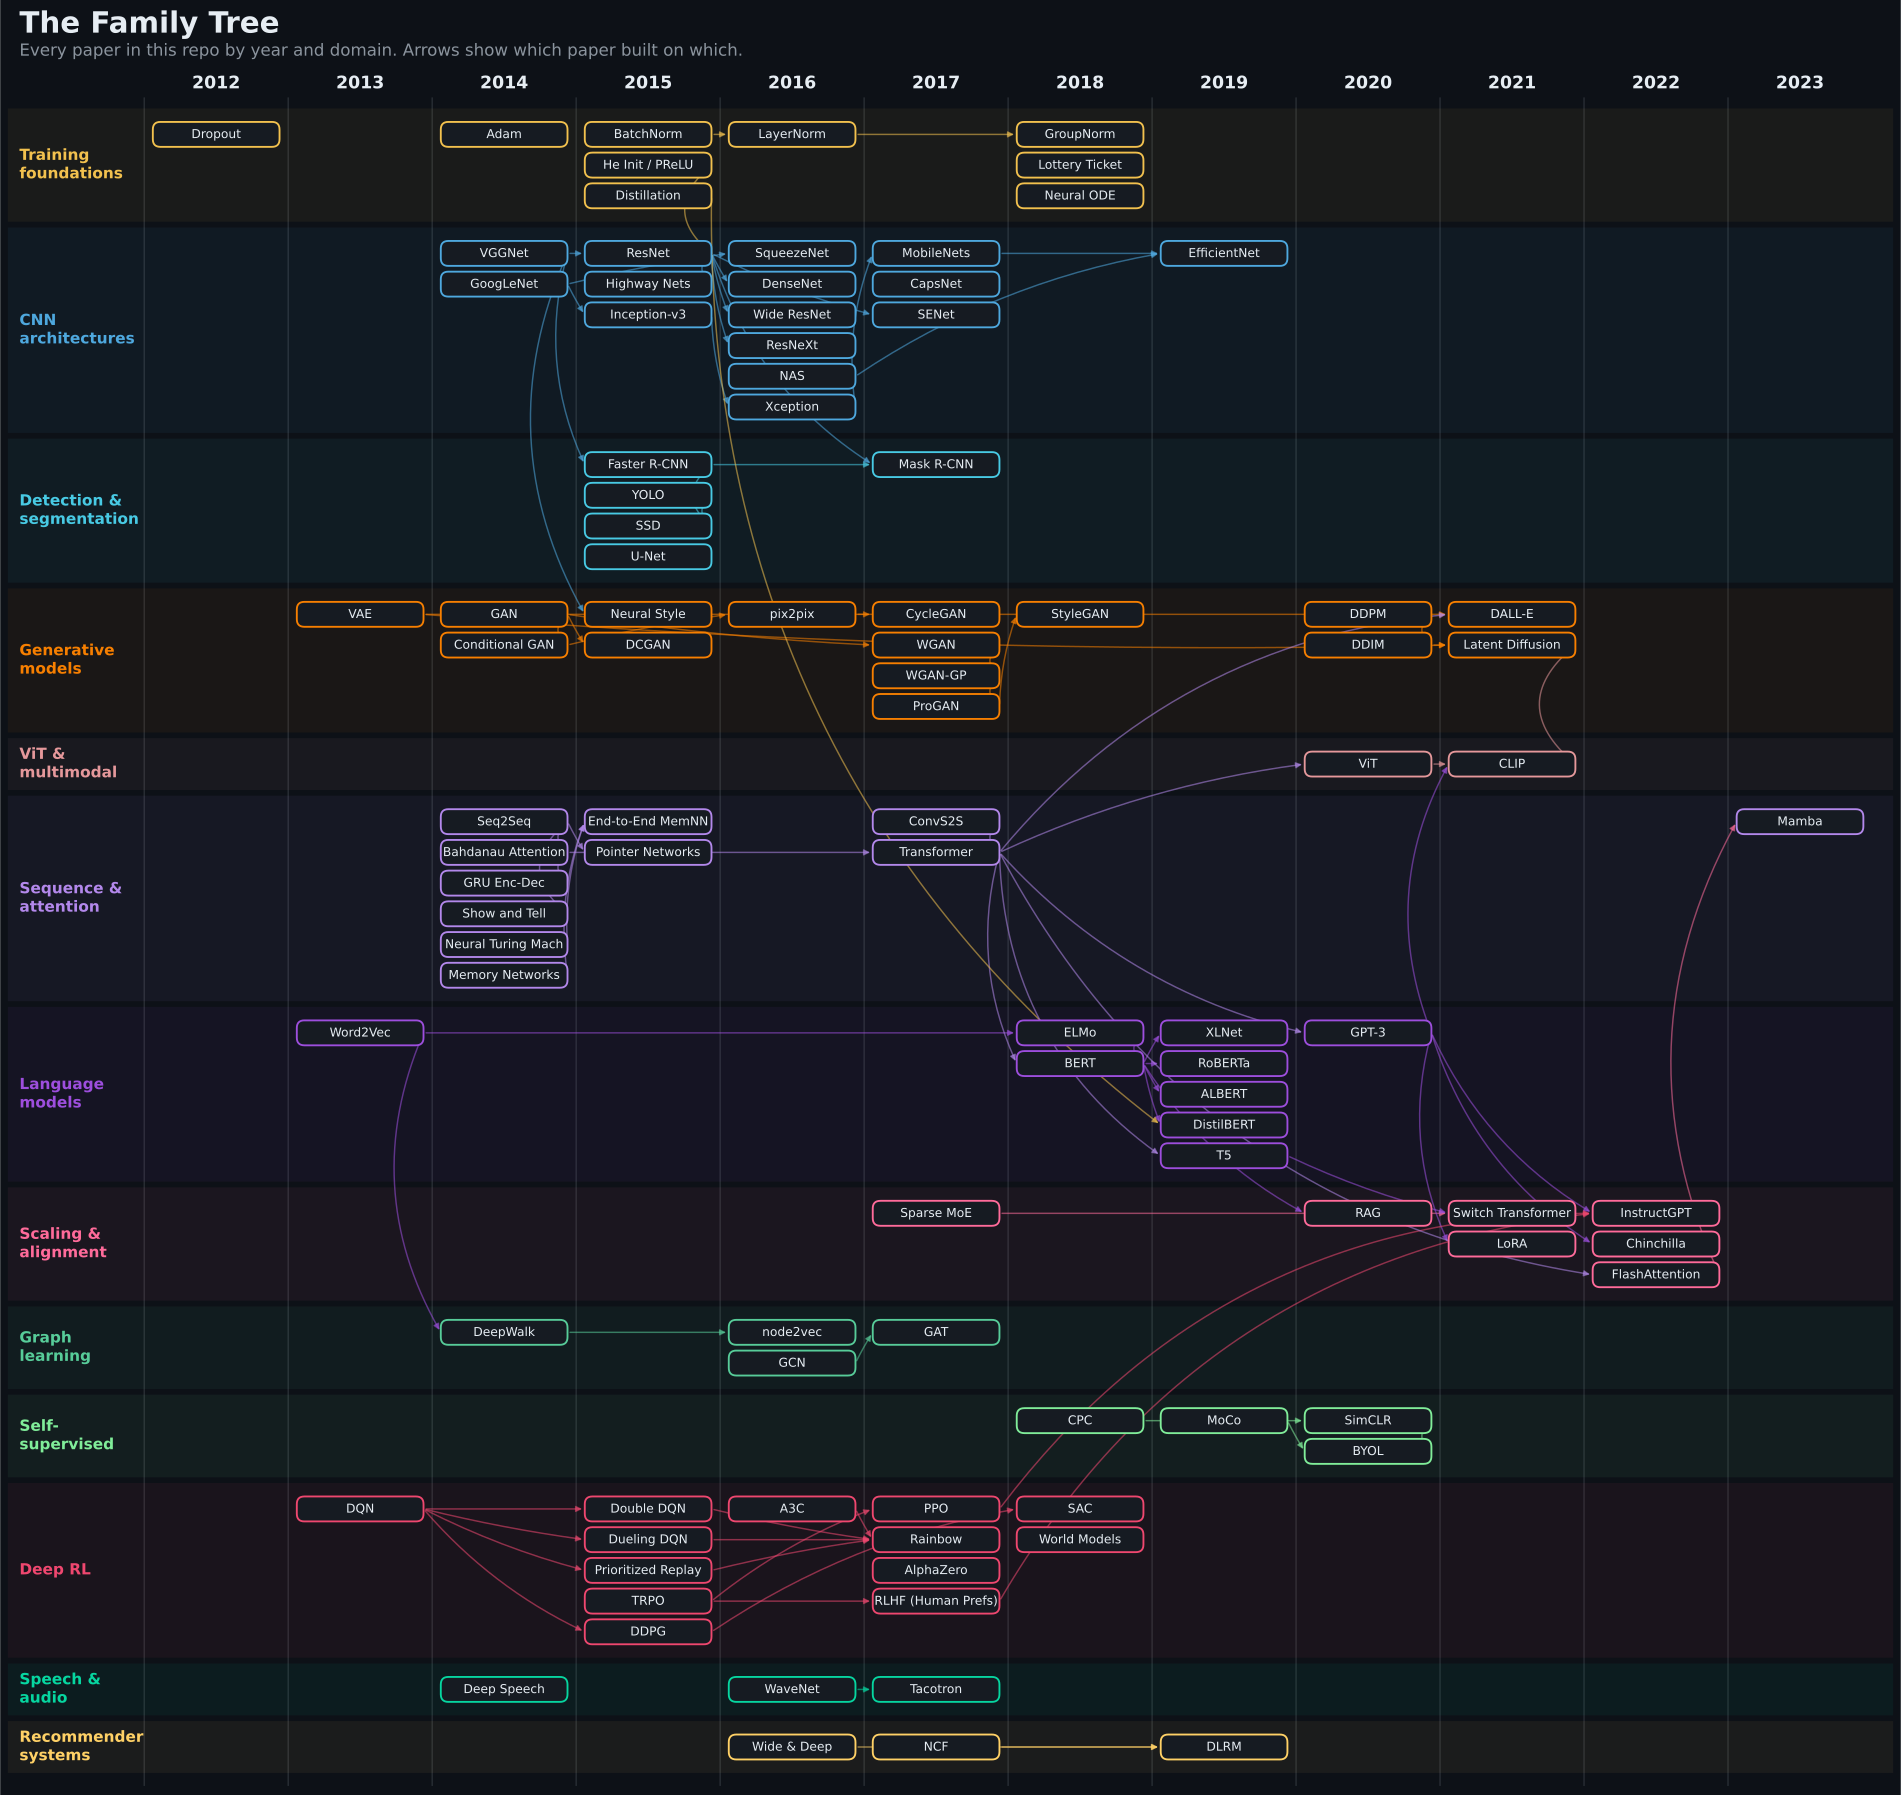
The family tree
What’s in each folder
| File | What it gives you |
|---|---|
README.md | A 5-minute read: summary, core idea, key method details, influence, and the problem explained like you’re 10 |
solution.ipynb | The from-scratch implementation, executed on Kaggle with all outputs |
CODE_ARCHITECTURE.md | A guided walkthrough of the notebook: data flow, tensor shapes, and simplifications vs. the paper |
TALK.md | Coverage, interview-style Q&A, common misconceptions, and citations |
Papers by domain
Training Foundations · Convolutional Architectures · Detection & Segmentation · Generative Models: VAEs, GANs, Diffusion · Vision Transformers & Multimodal · Sequence Models, Attention & Memory · Pretrained Language Models · Scaling, Efficiency & Alignment · Graph Representation Learning · Self-Supervised Learning · Deep Reinforcement Learning · Speech & Audio · Recommender Systems
Training Foundations
| # | Year | Paper | Run it |
|---|---|---|---|
| 002 | 2012 | Dropout — Improving Neural Networks by Preventing Co-adaptation of Feature Detectors |  |
| 003 | 2014 | Adam — A Method for Stochastic Optimization | |
| 006 | 2015 | Batch Normalization | |
| 007 | 2015 | Delving Deep into Rectifiers (He Initialization) | |
| 045 | 2015 | Distilling the Knowledge in a Neural Network | |
| 042 | 2016 | Layer Normalization | |
| 043 | 2018 | Group Normalization | |
| 046 | 2018 | The Lottery Ticket Hypothesis: Finding Sparse, Trainable Neural Networks | |
| 064 | 2018 | Neural Ordinary Differential Equations | |
Convolutional Architectures
Detection & Segmentation
| # | Year | Paper | Run it |
|---|---|---|---|
| 031 | 2015 | Faster R-CNN: Towards Real-Time Object Detection | |
| 032 | 2015 | You Only Look Once (YOLO) | |
| 033 | 2015 | SSD — Single Shot MultiBox Detector | |
| 035 | 2015 | U-Net: Convolutional Networks for Biomedical Image Segmentation | |
| 034 | 2017 | Mask R-CNN | |
Generative Models: VAEs, GANs, Diffusion
Vision Transformers & Multimodal
| # | Year | Paper | Run it |
|---|---|---|---|
| 081 | 2020 | An Image is Worth 16x16 Words (Vision Transformer) | |
| 082 | 2021 | Learning Transferable Visual Models From Natural Language Supervision (CLIP) | |
Sequence Models, Attention & Memory
| # | Year | Paper | Run it |
|---|---|---|---|
| 011 | 2014 | Sequence to Sequence Learning with Neural Networks | |
| 012 | 2014 | Neural Machine Translation by Jointly Learning to Align and Translate | |
| 013 | 2014 | Learning Phrase Representations using RNN Encoder-Decoder (GRU) | |
| 014 | 2014 | Show and Tell: A Neural Image Caption Generator | |
| 015 | 2014 | Neural Turing Machines | |
| 016 | 2014 | Memory Networks | |
| 017 | 2015 | End-to-End Memory Networks | |
| 018 | 2015 | Pointer Networks | |
| 019 | 2017 | Convolutional Sequence to Sequence Learning | |
| 020 | 2017 | Attention Is All You Need (Transformer) | |
| 100 | 2023 | Mamba: Linear-Time Sequence Modeling with Selective State Spaces | |
Pretrained Language Models
Scaling, Efficiency & Alignment
Graph Representation Learning
| # | Year | Paper | Run it |
|---|---|---|---|
| 066 | 2014 | DeepWalk: Online Learning of Social Representations | |
| 065 | 2016 | node2vec: Scalable Feature Learning for Networks | |
| 067 | 2016 | Semi-Supervised Classification with Graph Convolutional Networks (GCN) | |
| 068 | 2017 | Graph Attention Networks (GAT) | |
Self-Supervised Learning
Deep Reinforcement Learning
Speech & Audio
| # | Year | Paper | Run it |
|---|---|---|---|
| 094 | 2014 | Deep Speech: Scaling up End-to-End Speech Recognition | |
| 089 | 2016 | WaveNet: A Generative Model for Raw Audio | |
| 090 | 2017 | Tacotron: Towards End-to-End Speech Synthesis | |
Recommender Systems
| # | Year | Paper | Run it |
|---|---|---|---|
| 092 | 2016 | Wide & Deep Learning for Recommender Systems | |
| 091 | 2017 | Neural Collaborative Filtering | |
| 093 | 2019 | Deep Learning Recommendation Model (DLRM) | |
Year = first public release (usually arXiv). Numbers follow the order of the curated reading list.
Watch: Backprop Daily
Short videos on the same 100 papers: learn AI the way models learn, one step at a time. They’re made by an automated pipeline that writes the script, narrates it, generates the visuals and renders the video.
 GPT-3: AI That Learns From Just Few Examples notebook |  This AI Learned Video Games From Pixels: DQN Explained notebook |
 YOLO: AI Sees Everything in One Look notebook |  GANs: Two AIs Fight Until Fakes Look Real notebook |
 Attention Is All You Need: The Paper That Changed AI Forever notebook |
More at youtube.com/@BackpropDaily.
About me
I’m Nadeem Sajjad, a Senior AI Engineer and forward-deployed engineer with 12+ years across startups and scale-ups.
If this helped you understand a paper, a ⭐ helps others find it.
Licensed under the MIT License. Generated by scripts/build_readme.py from scripts/papers.tsv; edit those, not this file.